Model Comparison
The modelComparison function compares multiple context-specific models built from the same reference model. It runs a set of comparative analyses and stores the results under a dedicated comparisons field in the project structure.
Prerequisites
Single model analysis required
singleModelAnalysis must have been run on all models included in the comparison, and the active analysis must have been set for each model using chooseActiveAnalysisForComparison. The active analysis provides the FBA, FVA, and sampling results used by the functional and sampling comparisons.
Choosing the active analysis
Since multiple analysis runs (with different parameters) can coexist on the same model, the chooseActiveAnalysis function must be called before running modelComparison. It designates which analysis run to use for each model in the comparison by copying it into an active slot under project.models.<modelName>.analysis.active. This way, downstream comparison functions can access results without needing to know the exact analysis ID for each model.
[project, activeAnalysisTable] = chooseActiveAnalysis(project, modelList, analysisIDs, overwriteActive)
Input arguments
| Name | Type | Description | Default |
|---|---|---|---|
project |
struct |
Project structure with completed single model analyses | required |
modelList |
cell array |
Names of the models to define an active analysis for | required |
analysisIDs |
cell array |
Analysis ID to set as active for each model (same order as modelList) |
{} (most recent) |
overwriteActive |
cell array |
Fields to overwrite in the existing active slot, or {'all'} for full replacement |
{'all'} |
Output
| Name | Type | Description |
|---|---|---|
project |
struct |
Project with active analysis defined for each model |
activeAnalysisTable |
table |
Summary of the active analysis IDs used per model |
Behavior
- No
analysisIDsprovided — the most recent analysis (by timestamp) is automatically selected for each model. overwriteActive = {'all'}(default) — the entireactiveslot is replaced with the chosen analysis. All previous active results are discarded.overwriteActive = {'FBA', 'FVA', ...}— only the specified fields are replaced in the active slot. Other fields (e.g.sampling) are preserved. Theparameterstable is automatically merged: rows corresponding to the overwritten analyses are replaced, while rows for other analyses are kept.
Selective overwrite
If you want to update only the FBA results in the active analysis while keeping the existing sampling results, use overwriteActive = {'FBA'} instead of {'all'}. This avoids re-running the entire analysis pipeline.
Usage example
% Use the most recent analysis for each model
[project, activeTable] = chooseActiveAnalysis(project, {"model1", "model2"});

% Specify explicit analysis IDs
[project, activeTable] = chooseActiveAnalysis(project, {"model1", "model2"}, ...
    {"analysis_20240815_1430", "analysis_20240816_0900"});

% Selectively overwrite only FBA in the active slot
[project, activeTable] = chooseActiveAnalysis(project, {"model1"}, ...
    {"analysis_20240815_1430"}, {'FBA'});
Comparison types
Three types of comparison are available, each investigating a different aspect of the models:
| Comparison | Key | Description |
|---|---|---|
| Structural | structuralComparison |
Compares the presence or absence of reactions, metabolites, and genes across models. Includes Jaccard similarity, core reaction retention, and pathway-level reaction presence. Always run first — it is a prerequisite for the other two. |
| Functional | functionalComparison |
Compares the functional capacity of the models based on FBA and FVA results. Includes objective function values, exchange reaction fluxes, FVA similarity heatmaps, pathway enrichment for dissimilar reactions, and flux sum heatmaps per pathway. |
| Sampling | samplingComparison |
Compares the sampling solution spaces of the models. Includes ordered sample matrices, inter-model KL divergence (if available), and flux sum heatmaps from sampling distributions. Requires that sampling has been performed on all compared models. |
Structural comparison is mandatory
The structural comparison is always run, even if only functionalComparison or samplingComparison is requested. If a comparison with the same name and reference model already exists and the structural analysis has already been completed, it is not re-run — only the newly requested analyses are performed.
Function signature
[project, comparisonName] = modelComparison(project, modelList, referenceModel, identifier, analyses)
Input arguments
| Name | Type | Description | Default |
|---|---|---|---|
project |
struct |
Project structure with single model analyses completed | required |
modelList |
string array |
Names of the models to compare | required |
referenceModel |
string |
Name of the reference model used to compute relative reaction presence | required |
identifier |
string |
Postfix appended to the comparison name | current timestamp (_yyyyMMdd_HHmmss) |
analyses |
string array |
Analyses to perform (subset of structuralComparison, functionalComparison, samplingComparison, IDAREoutput) |
"structuralComparison" |
Output
| Name | Type | Description |
|---|---|---|
project |
struct |
The input project with a comparisons field added |
comparisonName |
string |
Name of the created comparison |
Comparison naming
The comparison name is built from the ordered list of compared models joined by _vs_, followed by the identifier:
model1_vs_model2_vs_model3__20240815_1430
Models are ordered according to their order of appearance in project.models, not the order in which they are passed to the function. This ensures consistent naming regardless of the input order.
Result storage
All comparison results are stored under:
project.comparisons.(comparisonName)
The following fields are populated:
| Field | Description |
|---|---|
modelNames |
Ordered list of compared model names |
referenceModel |
Name of the reference model used |
structuralComparison |
Structural comparison results and plots |
structuralAnalysisStatus |
Flag indicating whether structural analysis has been run (1 = done) |
functionalComparison |
Functional comparison results and plots (if requested) |
samplingComparison |
Sampling comparison results and plots (if requested) |
comparedAnalysisID |
Table mapping each model to the analysis ID used for the comparison |
Overwriting behavior
If a comparison with the same name already exists:
- Same reference model and structural analysis already run — only the newly requested analyses are performed; the structural comparison is reused.
- Different reference model — a warning is issued and the user is prompted to confirm overwriting. Answering
naborts the operation. To create a separate comparison instead, use a differentidentifier.
Example Comparative Analysis
Running the comparative metabolic model comparison
In the following, we are going to work with a breast cancer dataset to demonstrate how TackleMMe can be used to explore metabolic models.
The bulk RNA-seq data on which the models are based can be found here. The samples in this dataset were obtained from breast cancer patients at different stages of the disease. For the purpose of this tutorial, the patient samples were divided according to their disease stage. The comparative analysis performed in the following sections is therefore intended to provide initial insights into the metabolic differences associated with breast cancer disease progression.
The models shown here were generated based on data generated entirely by the TCGA Research Network: https://www.cancer.gov/tcga.
The prerequisites are that the Project Initialization and Single Model Analysis have been run beforehand. Let's walk through this example step by step.
The Single Model Analysis function added analysis slots to our models, which can be found here:
BRCAProject
 -> models
    -> StageI
        -> analysis
    -> StageII
        -> analysis
  ...
To see which analyses are available for each model, you can visualize the analysis object:
BRCAProject.models.StageI.analysis
Let's choose the analyses we want to compare with one another first.
initCobraToolbox();
changeCobraSolver('gurobi');
feature astheightlimit 2000;

dataPath = "path/to/ProjectObject";
load(dataPath + filesep +'BRCAProjectNo3.mat')

modelsToCompare = {'Control', 'StageI', 'StageII', 'StageIV'};
[BRCAProject, analysisIDs] = chooseActiveAnalysis(BRCAProject, modelsToCompare);
The only thing that has changed in our BRCAProject is that the analysis of all the models defined in modelsToCompare now has an active analysis slot. The data in this slot will be used in the following steps to perform the comparative analysis.
So, let's perform the comparative analysis next:
% we define which model in our project.models slot is the model that was used to generate the context specific models from
referenceModel = "consistentMediumConstrainedModel";
% define which of the analysis you want to perform, by default the structuralComparison is always performed
comparisonList = ["structuralComparison", "functionalComparison", "samplingComparison"];

compID = "tutorial_BRCA_TackleMMe";

% this needs to be done since in the cobratoolbox there is already a function named modelComparison
rmpath("local/path/to/cobratoolbox/papers/2025_bioenergeticPD")

% and this is our main comparison function
[BRCAProject, comparisonName] = modelComparison(BRCAProject, modelsToCompare, referenceModel, compID, comparisonList);
This might take some time, depending on which comparisons are run. While the structural and functional comparisons are relatively quick, the samplingComparison can take some time to compute.
Here are some additional examples of how the function can be used:
% Run only the structural comparison (default)
[project, compName] = modelComparison(project, ...
    ["model1", "model2", "model3"], "model1");

% Run structural and functional comparisons with a custom identifier
[project, compName] = modelComparison(project, ...
    ["model1", "model2"], "model1", "batchA", ...
    ["structuralComparison", "functionalComparison"]);

% Run all three comparisons
[project, compName] = modelComparison(project, ...
    ["model1", "model2", "model3"], "model1", "fullRun", ...
    ["structuralComparison", "functionalComparison", "samplingComparison"]);
Downstream Investigation of the Metabolic Modelling Comparison
After running the pipeline, there are two main steps left in this tutorial:
- Default: Checking the visualizations that are generated by default by the pipeline
- Exploration: Generating additional figures using the pipeline functions for a more in depth exploration
Visualizations Created by Default by TackleMMe
The visualizations created by default serve two main purposes:
- Quality Control: Are the imports and exports reasonable, and does the difference in objective value make sense for the different models?
- Determining pathways of interest: Identifying pathways that may be of interest for further investigation.
Quality Control:
Growth rate in our models:
showFigure(BRCAProject.comparisons.(comparisonName).functionalComparison.plots.objValue)
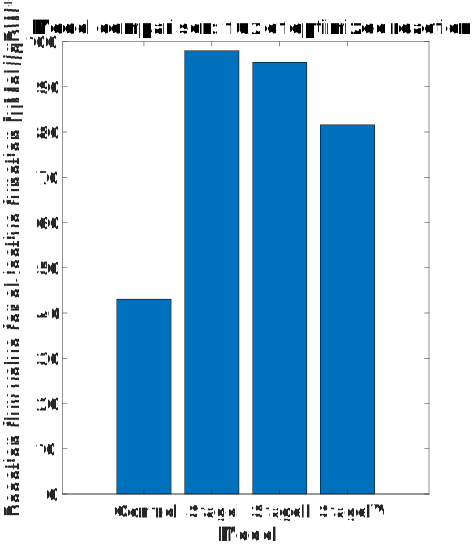
As expected, cancer cells proliferate more compared to the Control model.
The next question is: On what does the model grow/what does it produce ?
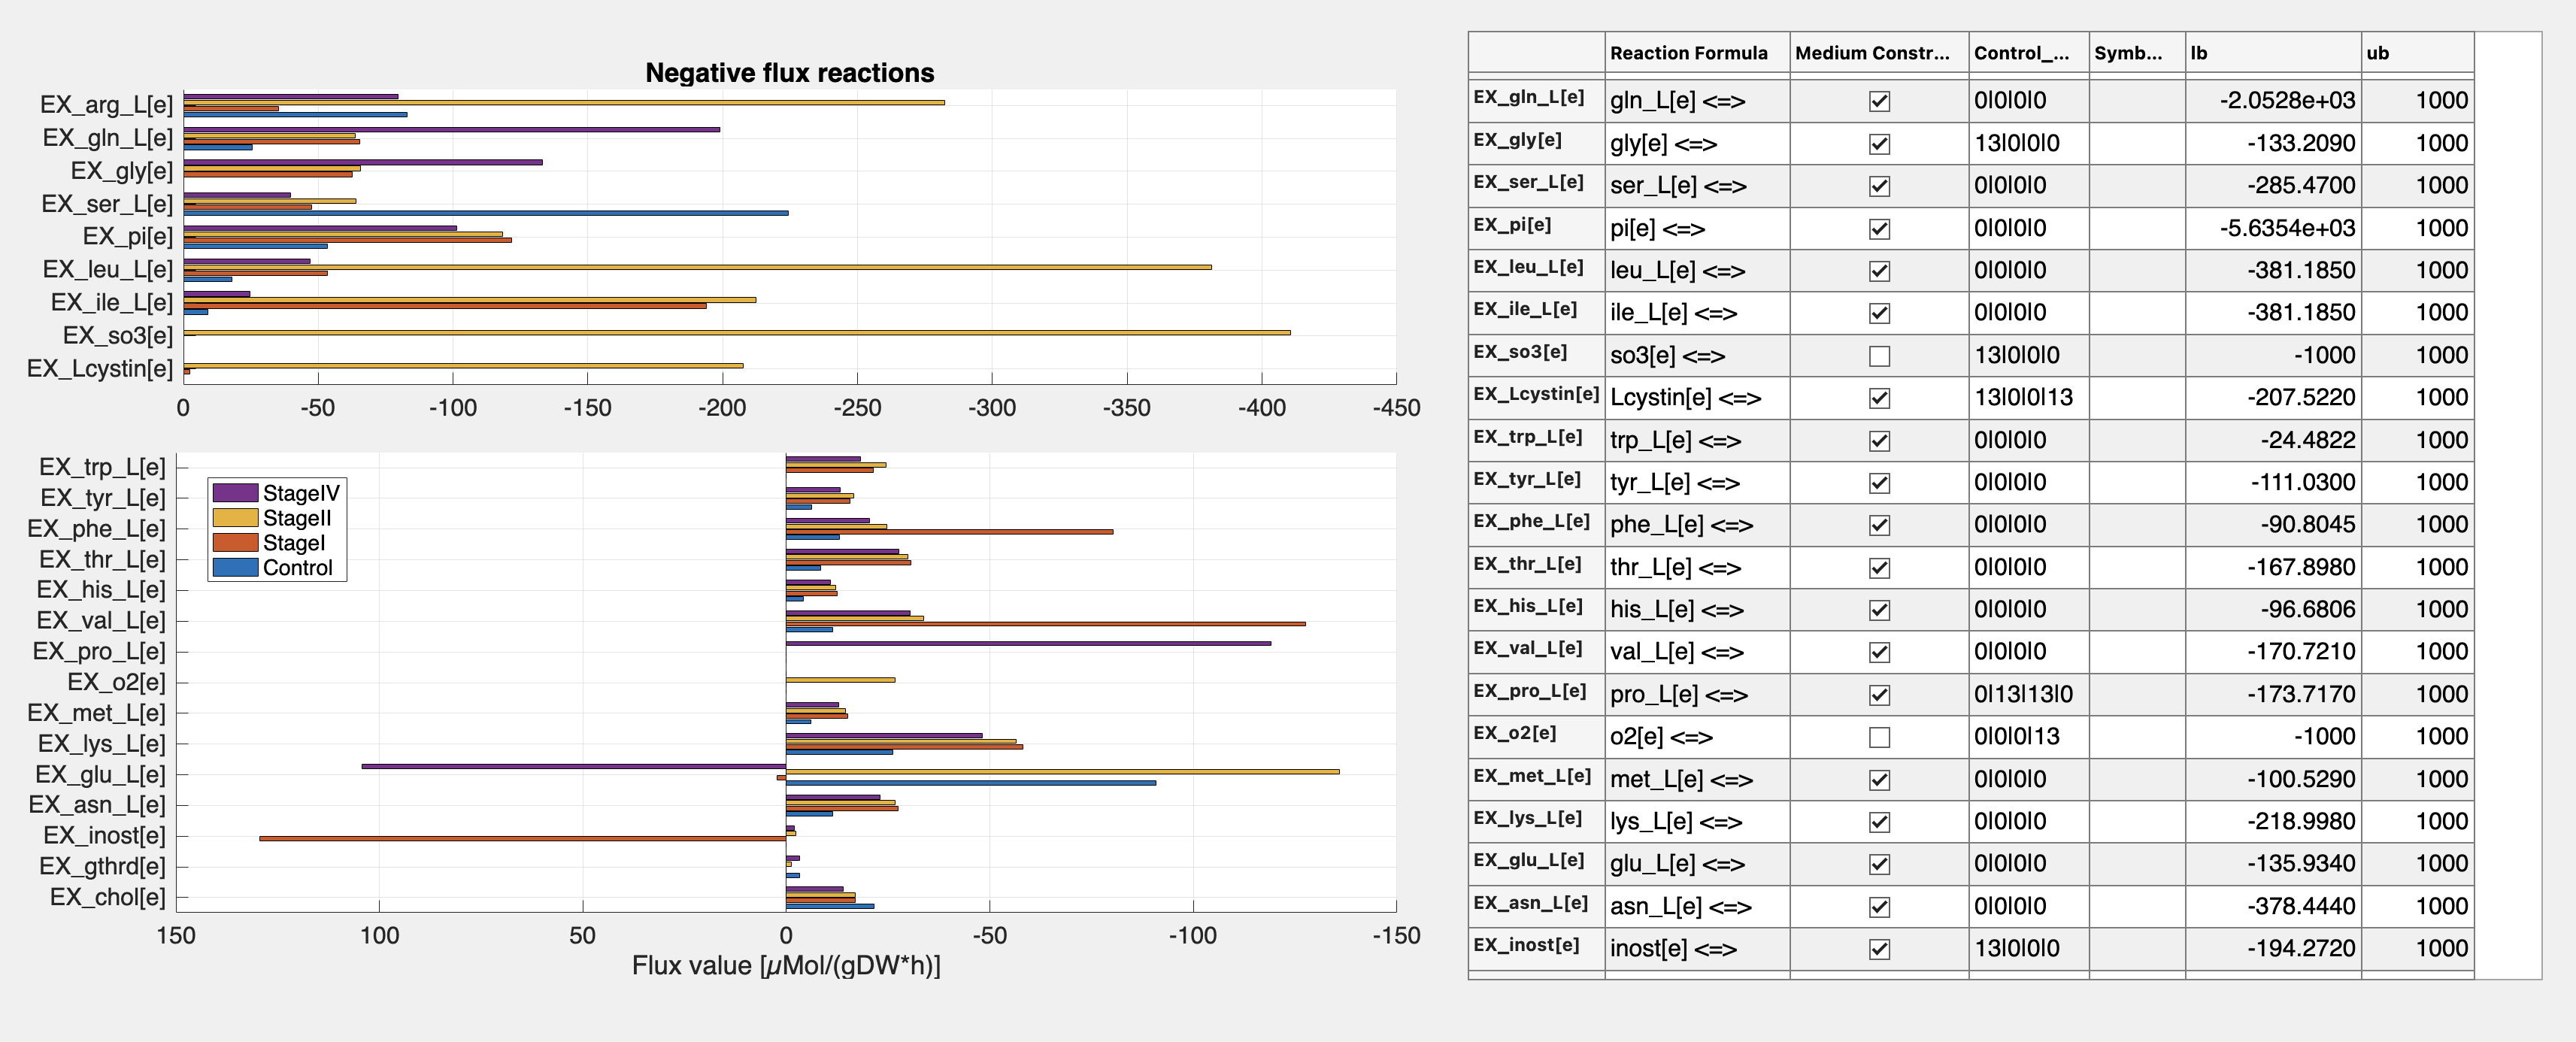
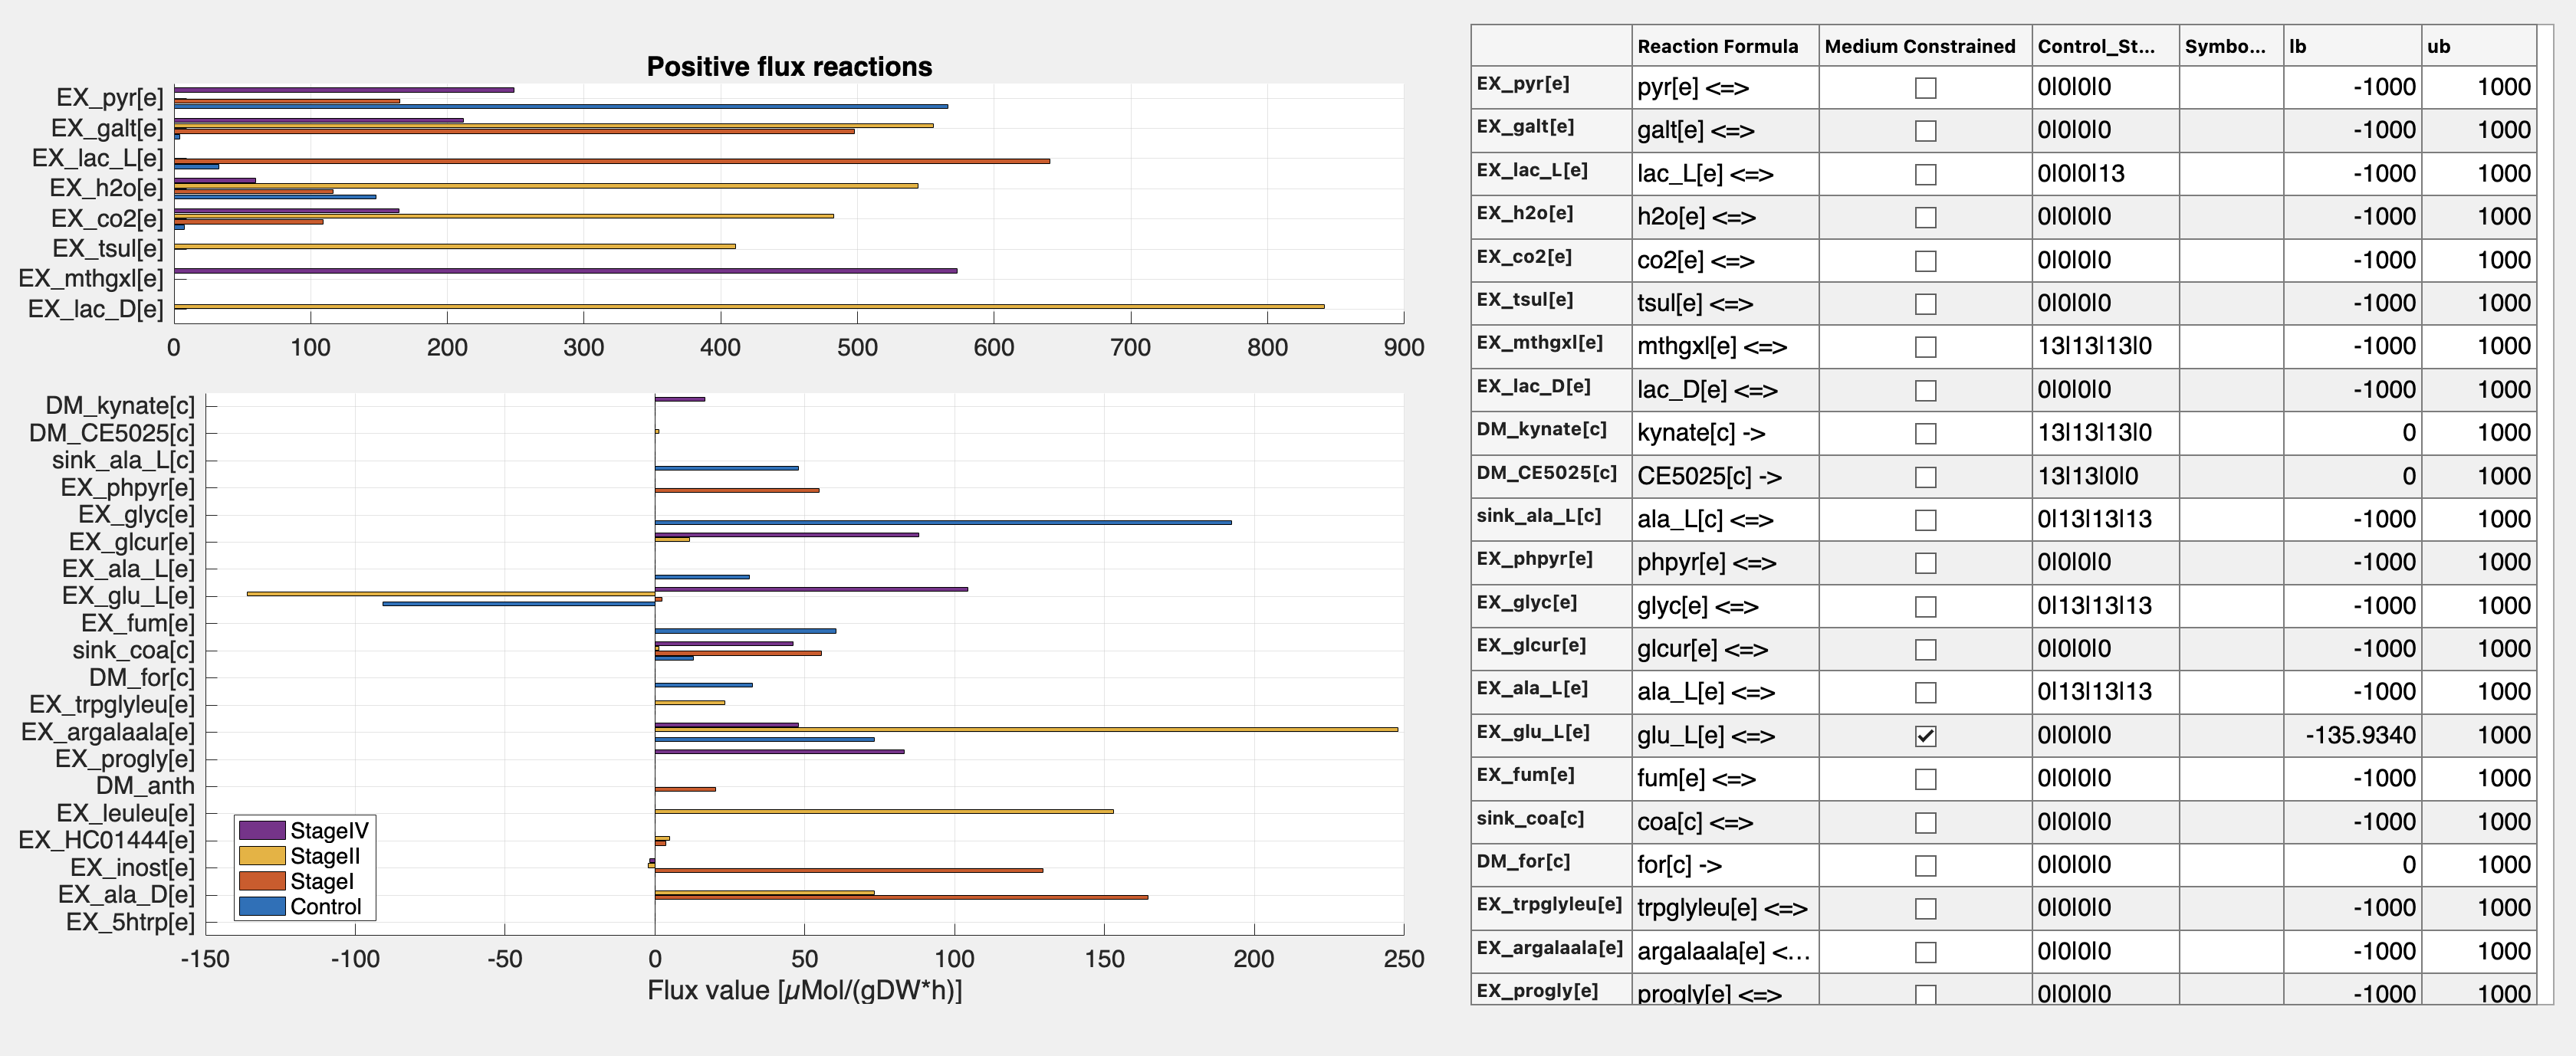
For models generated with rFASTCORMICS_v2, there are additional QC metrics to consider:
- How was our gene expression data discretized?
- How does this translate to the discretization at the reaction level?
- How many of the reactions are defined as active in each model?
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.dataDiscretization)
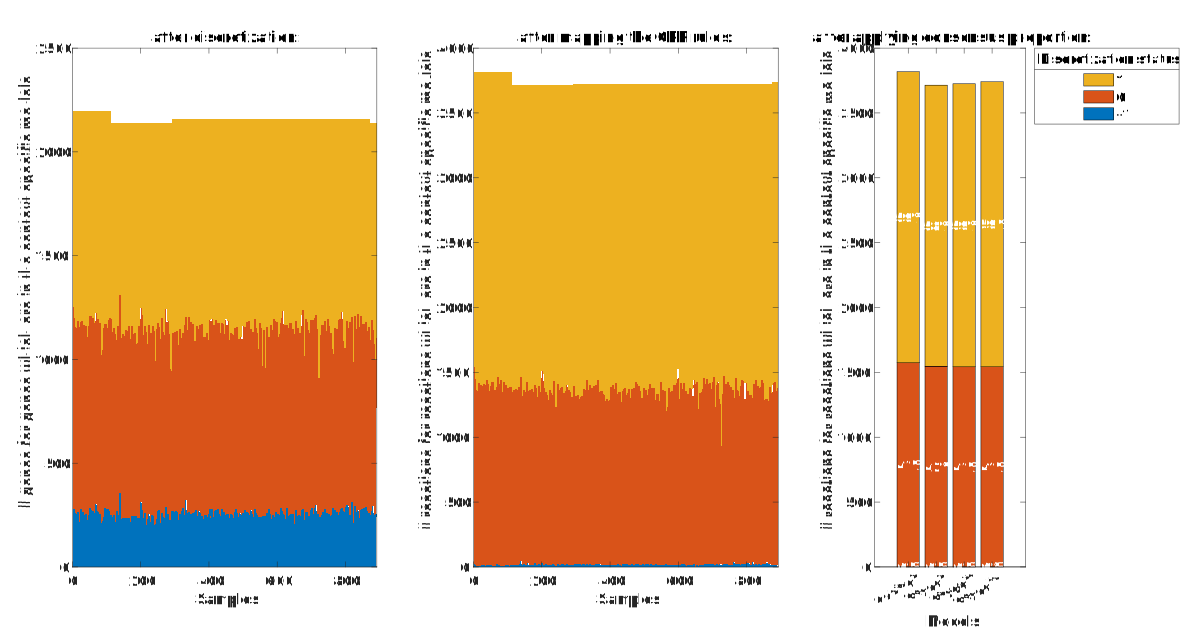
Here, you want a substantial proportion of your genes (left) and reactions (middle) to be discretized as 1. If you observe a high percentage of genes being discretized as -1 (e.g., 80% being -1), then something may have gone wrong during the discretization. In this case, you should go back and check the discretization figures generated by discretizeFPKM.m (see the code here), which is run as part of Tutorial Script No. 1 (see here).
The percentage of reactions assigned to each discretization status for each model (right subfigure) is influenced by both the reaction mapping (middle figure) and the applied consensus proportion. The consensus proportion defines the percentage of samples that need to have a value of 1 for a reaction to be categorized as a core (1) reaction. Therefore, if the percentage of reactions classified as 1 is low in the right subfigures, you can go back and apply a different consensus proportion. The default value is 90%.
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.coreReactions)
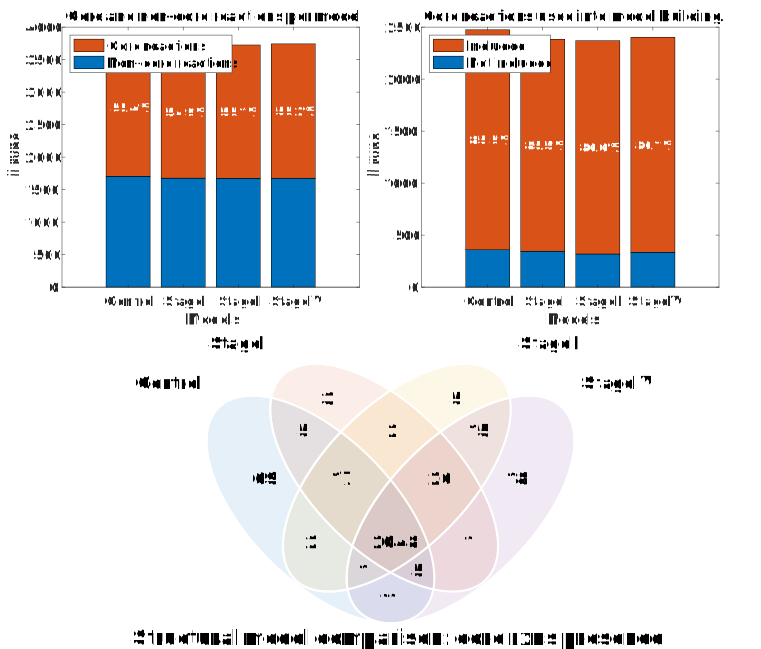
The behaviour of the models generated by rFastcormicsv2 are heavily dependend on the definition of the core reactions. Therefore two interesting metrics to look at are:
- How many of the rxns in a model are core reactions ? -> left upper figure
- How many of the rxns that were defined to be core reactions made it into the model ? -> right upper figure
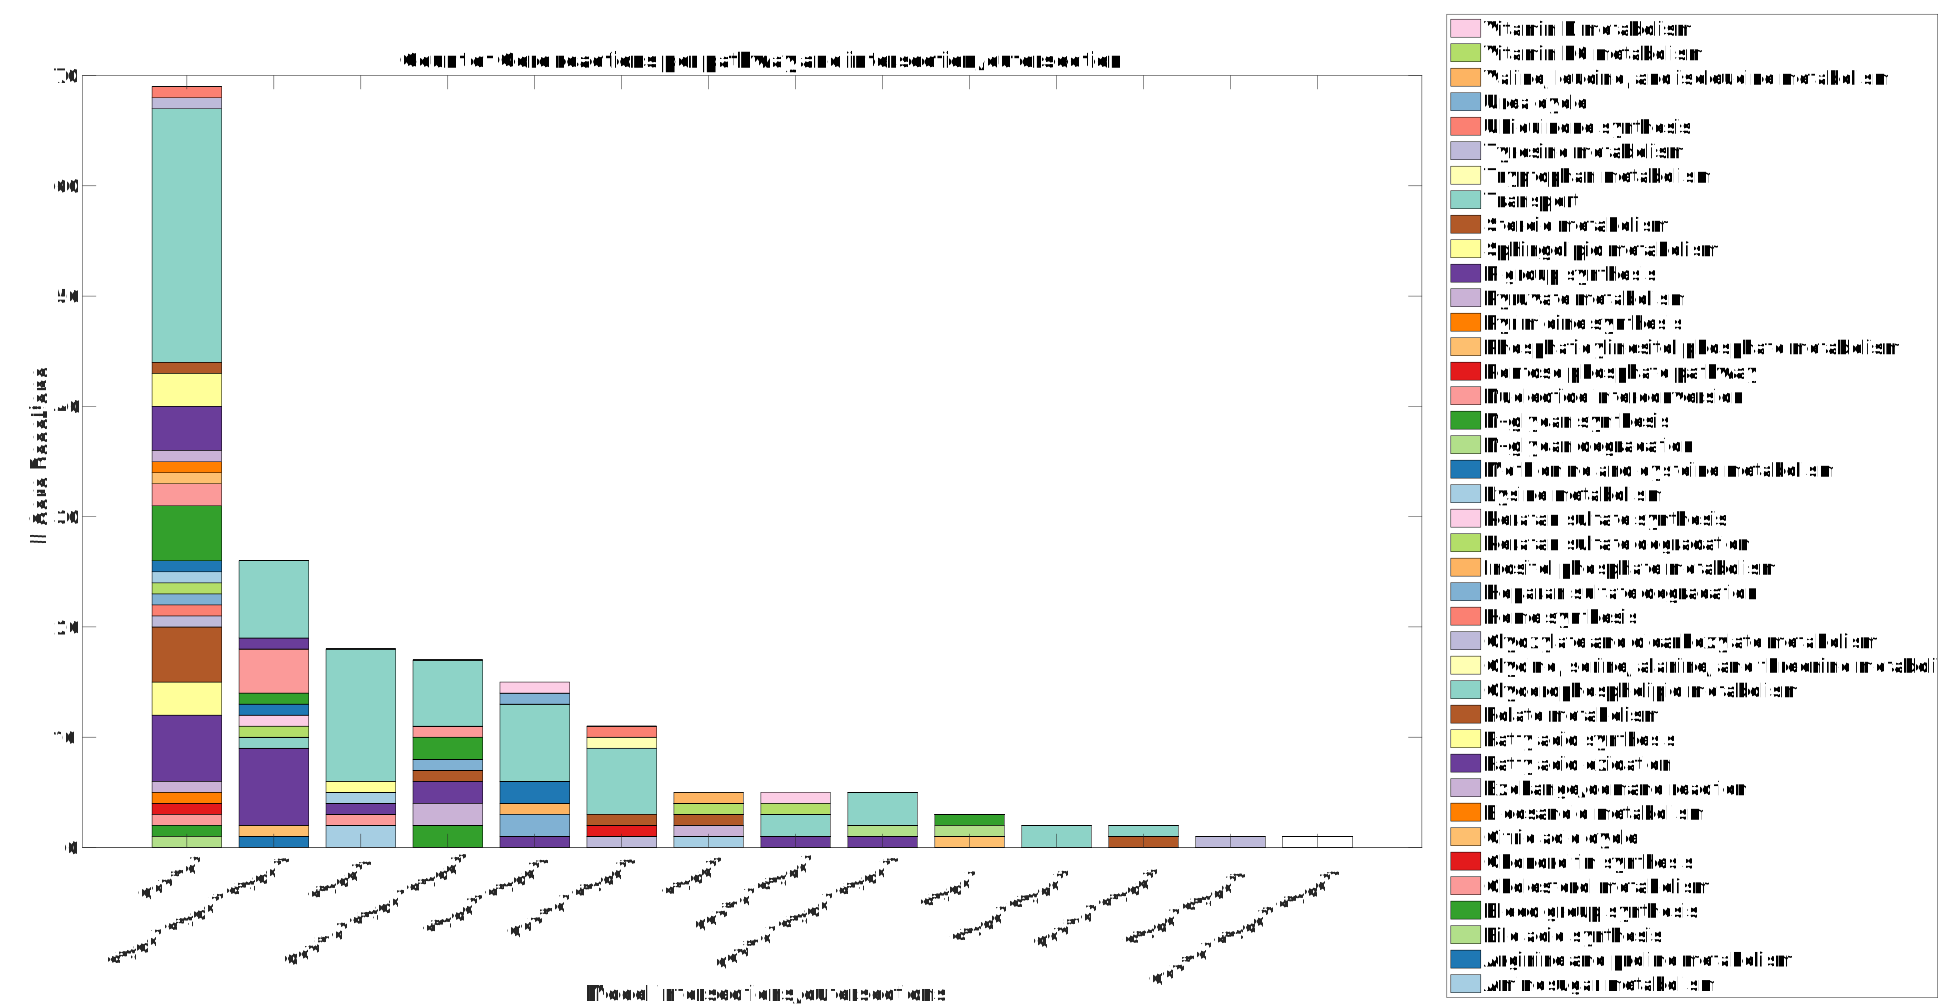
Optimally, we would like all of our core reactions to be included in our models, but in reality, this is not the case. Therefore, a trade-off between the size of the models and the number of core reactions included needs to be found. The more core reactions that are included in the model, the larger the model becomes, since forcing all core reactions into the model requires additional non-core reactions to be added in order to maintain model consistency. The overlap of the core reactions between the models is shown in the lower plot. Since the core reactions heavily influence the construction of the model (in addition to the medium), this figure provides a first impression of the extent of the differences between the models. In particular, it gives an indication of how many reactions are responsible for the overall structural differences observed between the models.
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.coreReactionsIntersections)
Structural Model Comparison:
After making sure that the QC metrics of our models look good, let's move on to take a closer look at what makes our models structurally different.
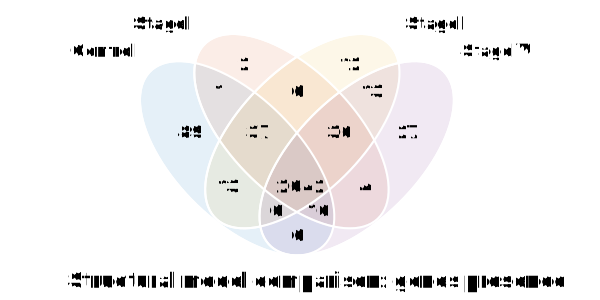
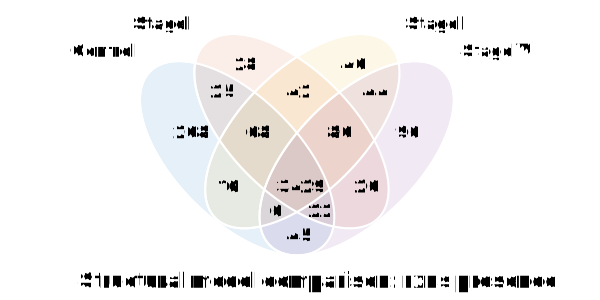
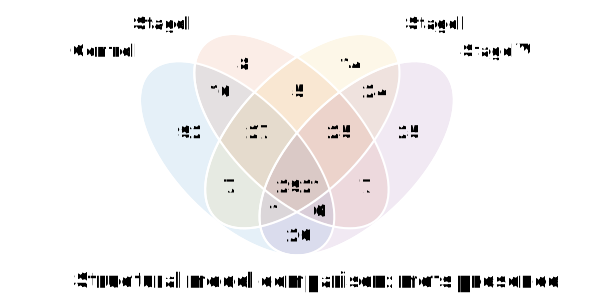
Intersection between models in absolute numbers:
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.intersections.genes)
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.intersections.rxns)
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.intersections.mets)
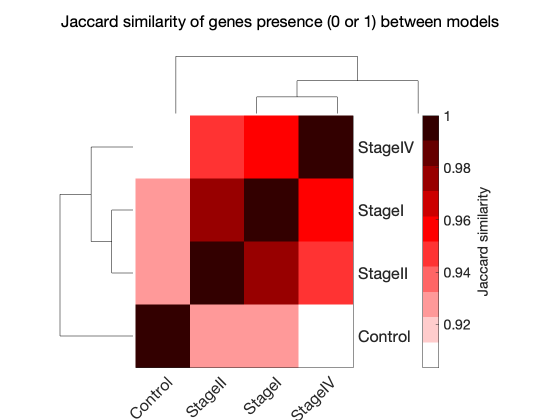
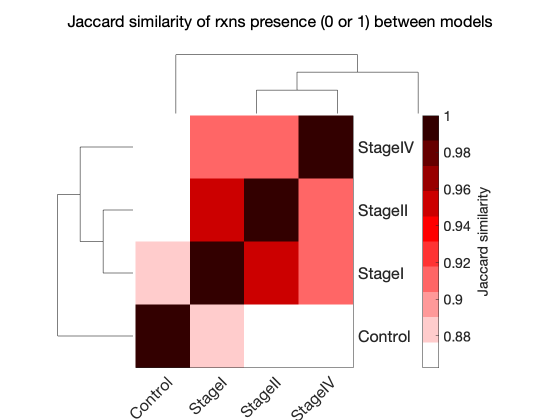
Similarity between the model defined by the Jaccard Similarity (1-Jaccard Distance):
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.jaccardDist.genes)
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.jaccardDist.rxns)
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.jaccardDist.mets)
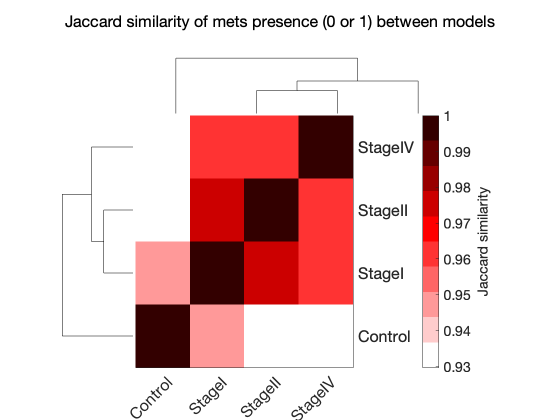
The hierarchical clustering shows that the cancer samples cluster together, as expected.
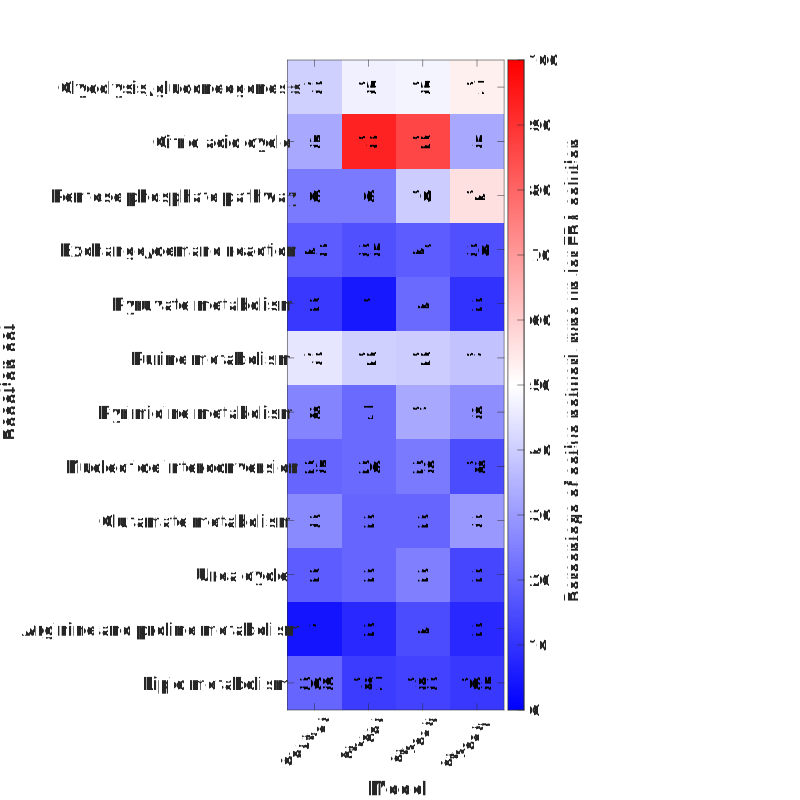
Next, the overlap between the models per subsystem is shown using both absolute values (numbers displayed in the tiles) and relative values (tile coloring), in the context of the pathway size (#rxns):
showFigure(BRCAProject.comparisons.(comparisonName).structuralComparison.plots.reactionPathwayPresence)
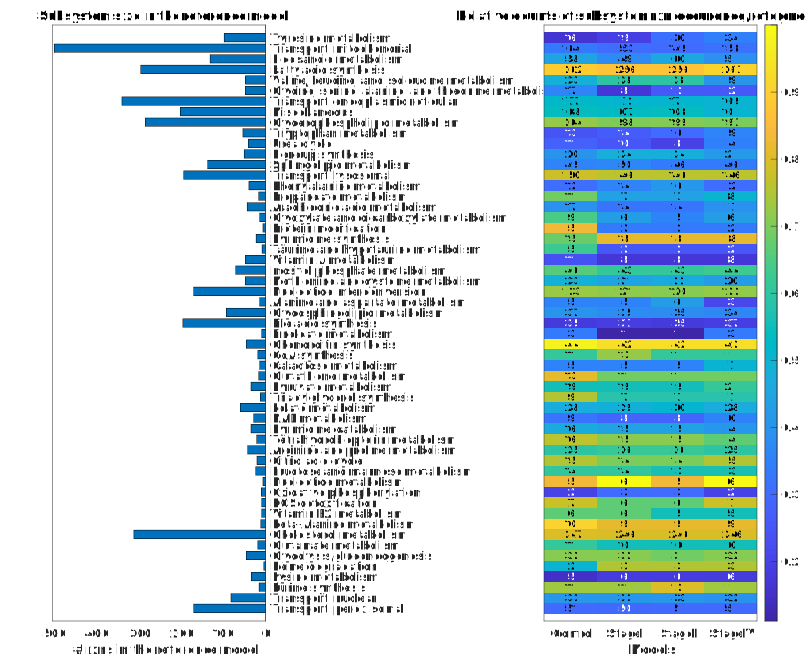
In this figure that shows the count of rxns per subsystem, we see that the
Functional Model Comparison:
The functional comparison answers the following questions:
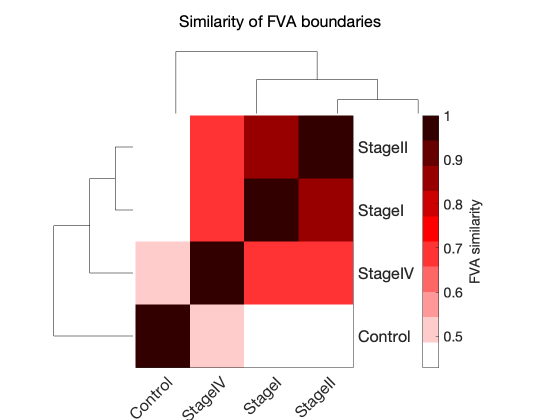
- How different are the FVA boundaries between the models?
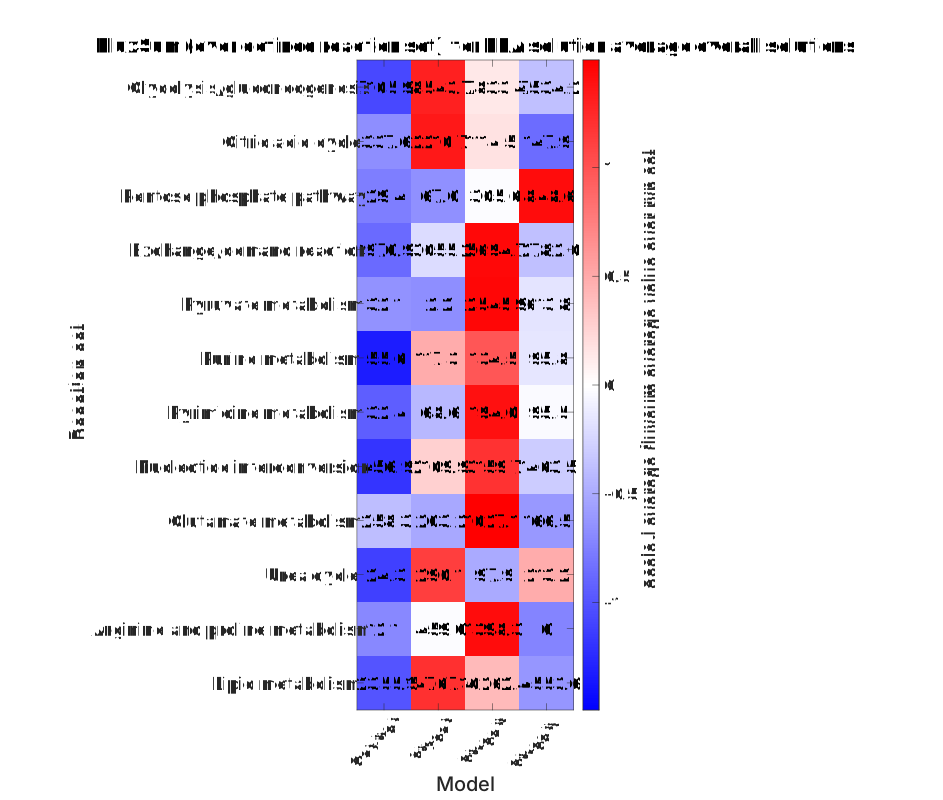
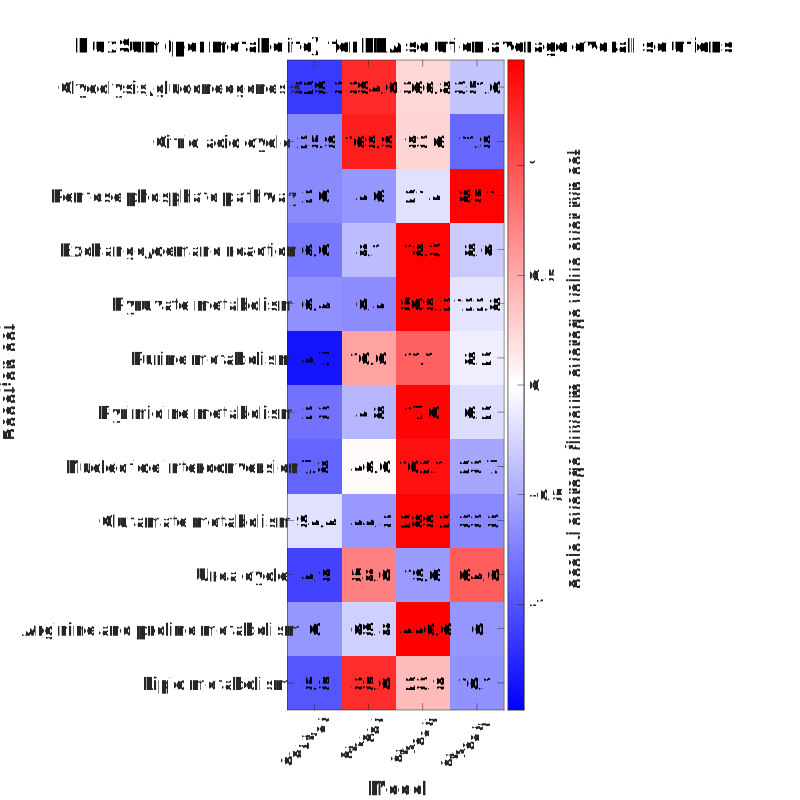
- Are there differences in reaction/metabolite usage (Fluxsum) per subsystem between the models?
- Are there differences in reaction usage (cardinality) per subsystem between the models?
showFigure(BRCAProject.comparisons.(comparisonName).functionalComparison.plots.fvaSim.overall)
showFigure(BRCAProject.comparisons.(comparisonName).functionalComparison.plots.fba.heatmapRxnFluxsum)
showFigure(BRCAProject.comparisons.(comparisonName).functionalComparison.plots.fba.heatmapMetsFluxsum)
showFigure(BRCAProject.comparisons.(comparisonName).functionalComparison.plots.fba.heatmapRxnActivityFba)
These figures show that the TCA cycle is more active in the Stage I and Stage II models compared to the Control and Stage IV models. This pattern is consistent across Fluxsum of metabolites/reactions and Cardinality.
Sampling Comparison:
The sampling comparison investigates the broader solution space using flux sampling (by default, CHRR). Unlike FVA, which compares maximum and minimum flux capacities, sampling also assesses the likelihood and stability of different flux values within the feasible solution space.
Since less than half of the reactions are active in the FBA solution, FBA may provide limited insight into subsystems that are inactive when optimizing for the biomass_reaction. Sampling under a biomass constraint (by default, 90% of the biomass upper bound) therefore provides a broader view of the metabolic model and the stability of the flux values observed in the FBA solution.
showFigure(BRCAProject.comparisons.(comparisonName).samplingComparison.plots.heatmapRxnFluxSum)
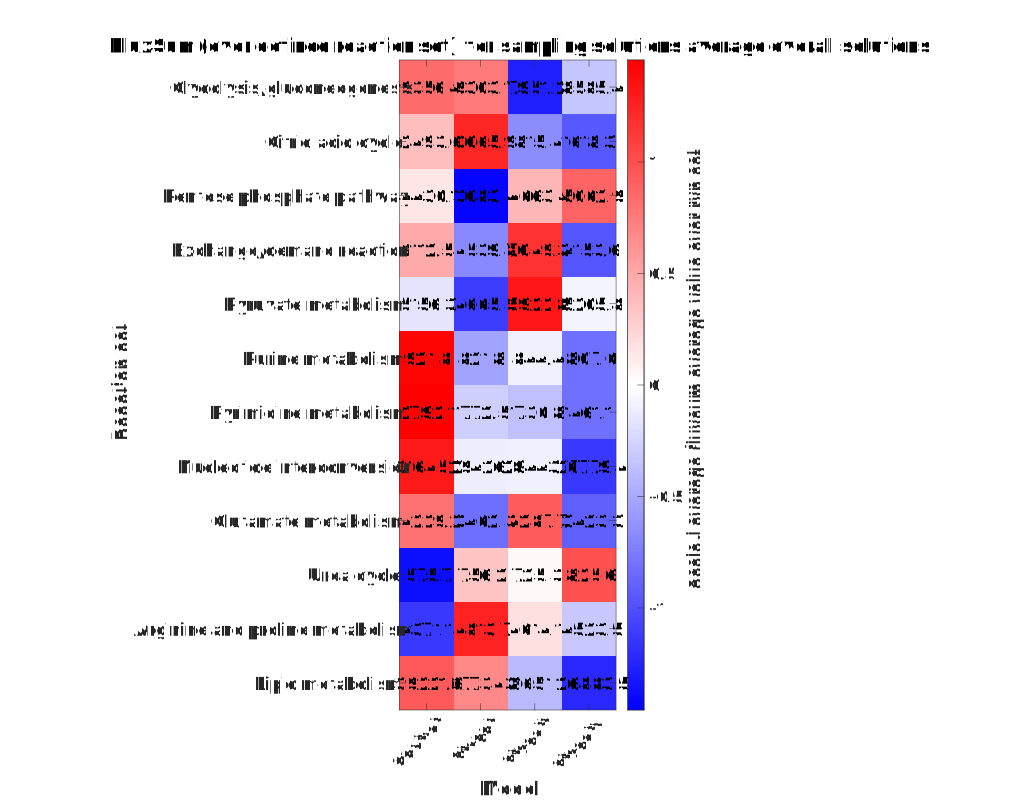
showFigure(BRCAProject.comparisons.(comparisonName).samplingComparison.plots.heatmapRxnFluxSumSamples)
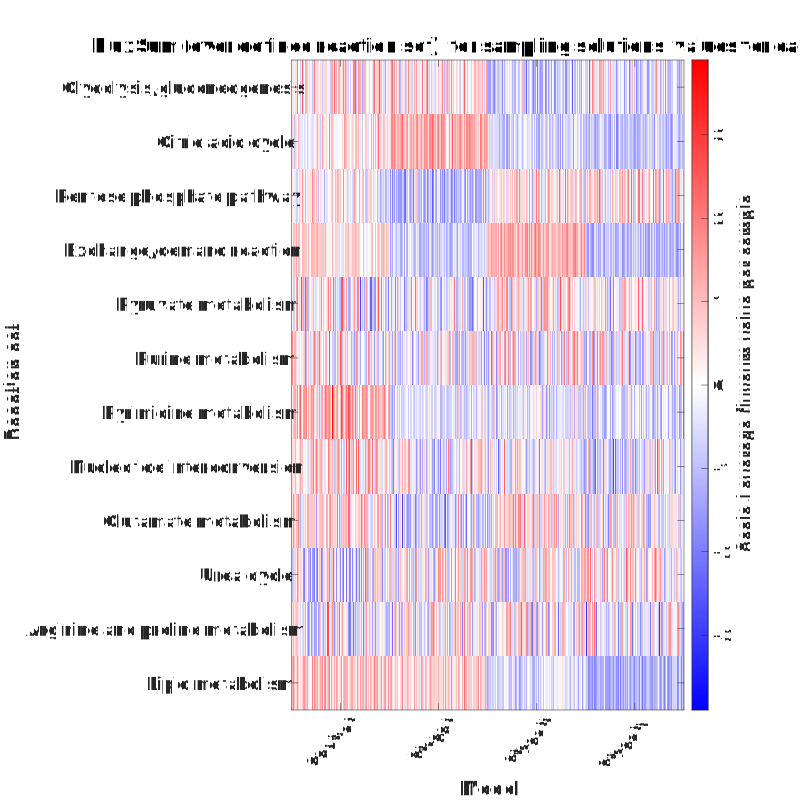
showFigure(BRCAProject.comparisons.(comparisonName).samplingComparison.plots.heatmapMetsFluxSum)
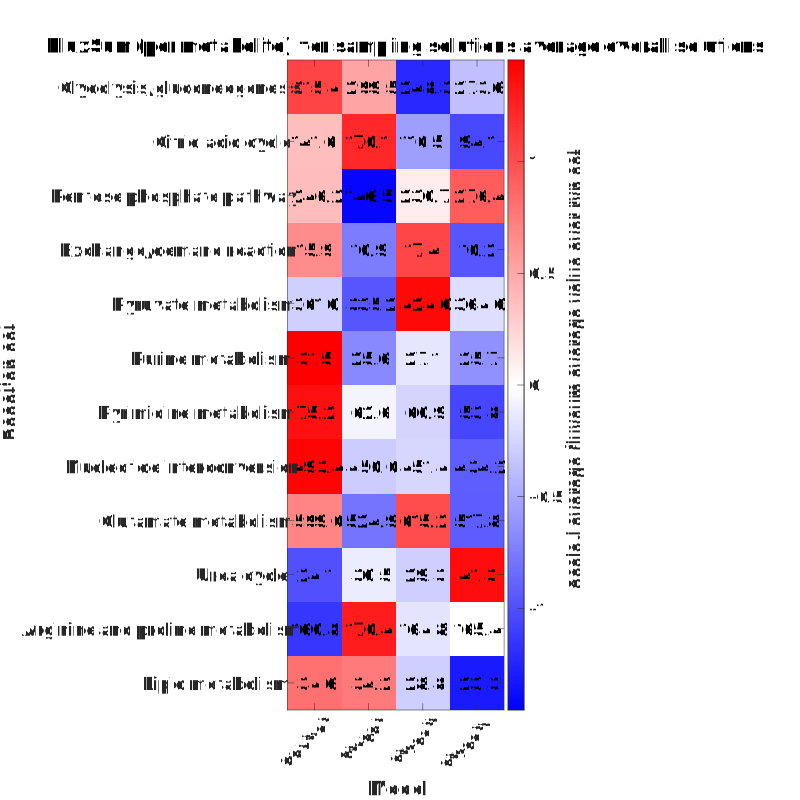
showFigure(BRCAProject.comparisons.(comparisonName).samplingComparison.plots.heatmapMetsFluxSumSamples)
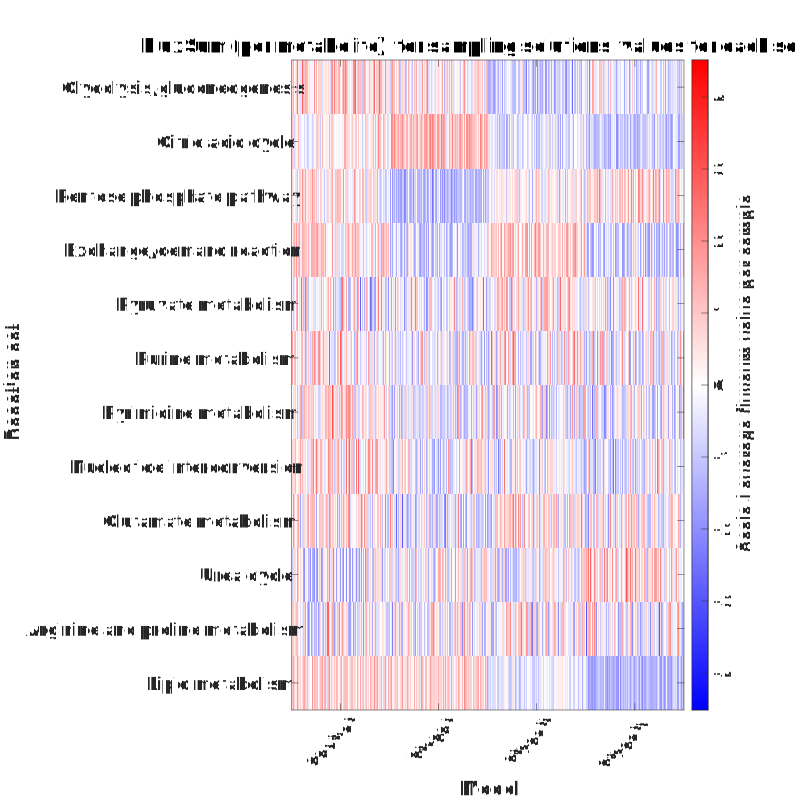
Going through the Fluxsum heatmaps generated from the sampling analysis, we see that the tendency observed for the TCA cycle is not reproduced here. We do not observe the same pattern across the models. This could be due to several reasons, and further investigation may help us understand why.
After looking through all the figures, we have a rough first overview of our model. As a next step, the exploratory part begins, where we look in more detail at our metabolic models. This exploratory analysis might be driven by certain pathways of interest for which we want to see whether biological assumptions are supported by the model. Alternatively, specific pathways might already stand out in the heatmaps we have generated because they show greater differences than others.
Exploration of metabolic models using TackleMMe
As established in the previous section we see some interesting tendencies for the TCA cycle. Looking at the Fluxsum plots (see Fig. 18), it can be seen that the Citric Acid Cycle tends to have higher values in Stage I, lower values in the Control, and even lower values in the Stage II and Stage IV models. In Fig. 19, we can also see that this difference is consistently observed across the samples. Using the functions provided by TackleMMe, it is easy to take a closer look at the individual pathways.
Taking a closer look at specific subsystems or specific sets of rxns can help to understand why.
As a first step, we want to obtain the rxnIDs of all reactions that are part of the pathways of interest:
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.*"; "Glycolysis.*"]);

visSingleRxnSamplingDistribution(BRCAProject, comparisonName, rxnsMetId(1), ["TCA"], referenceModel)
Flux distribution for all rxns that are part of the defined Rxn Set (here the TCA cycle and the Glycolysis).
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.*"; "Glycolysis.*"]);

visSingleMetSamplingDistribution(BRCAProject, comparisonName, rxnsMetId(1), ["TCA"], referenceModel)
Fluxsum distribution for all metabolites that participate in the rxns that are part of the defined Rxn Set (here the TCA cycle and the Glycolysis). This shows you the usage of a given metabolite in a set of rxns.
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.*"; "Glycolysis.*"]);
visSingleRxnFBA(BRCAProject, comparisonName, rxnsMetId(1), "FVA", false, "thresholdFlux", "none")
visSingleRxnFBA(BRCAProject, comparisonName, rxnsMetId(1), "FVA", true, "thresholdFlux", "none")
Visualizing the FVA and FBA values for a given Rxn Set.
getRxnIDs function:
The getRxnIDs function allows you to step through your network by giving in the subsystems,genes, rxns names you want to visualize. Here a few examples on how to use it:
% all rxns that are in the TCA cycle AND associated to SDH.* gene
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.* & ^SDH.*"]);

% all rxns that are in the TCA cycle OR associated to SDH.* gene
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.* | ^SDH.*"]);

% all rxns that are in the TCA cycle AND are connected to a metabolite in the mitochondria
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Citric acid.* & .*[m.*"]);

% all reaction where the udpg[c], gluside_hs, or g1p[c] participate
[rxnsMetId,producingMet,matched] = getRxnIDs(BRCAProject,referenceModel, ["udpg[c.* | EX_.*gluside_hs.* | g1p[c"]);

% visualize the fluxsum of fadh2 in differen subsystems
[rxnsMetId,producingMet,matched] = getRxnIDs(BRCAProject,referenceModel, ["fadh2[.* & Glycolysis.*","fadh2[.* & Pentose.*",...
                                                                              "fadh2[.* & Arginine and proline.*", "fadh2[.* & Citric acid cycle",...
                                                                              "fadh2[.* & Urea cycle", "fadh2[.* & Oxidative phosphorylation",...
                                                                              "fadh2[.* & Glutamate metabolism", "fadh2[.* & Glutathione metabolism"]);
visDiffMetSetUsageFBA(BRCAProject, comparisonName, rxnsMetId, ["fadh2 in Glycolysis", "fadh2 in PPP", "fadh2 in Argining and Proline metabolism", "fadh2 in TCA", "fadh2 in Urea cycle", "fadh2 in OxPhos", "fadh2 in Gluatamte metabolilsm", "fadh2 in Glutathione metabolism"], referenceModel)
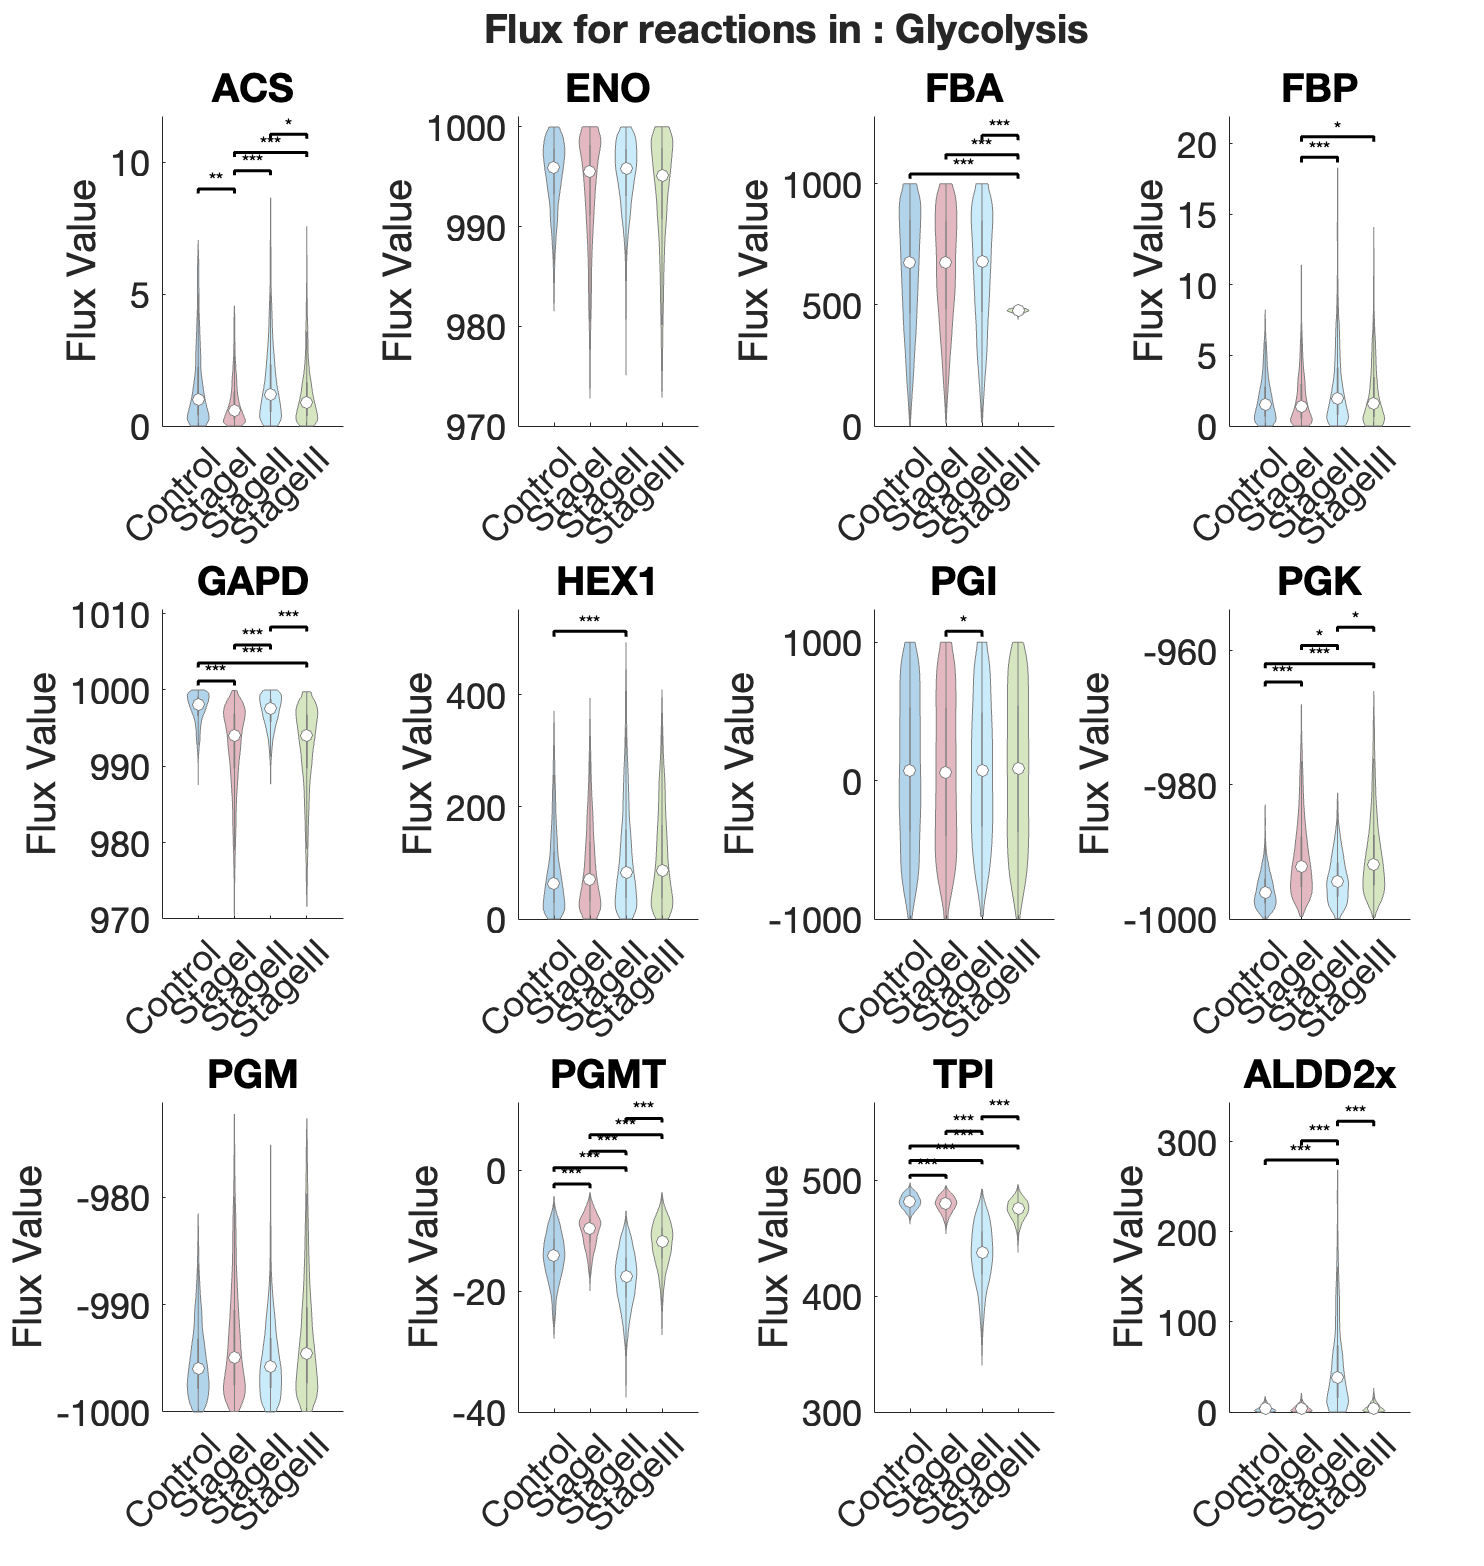
Visualization of significanly different rxn distributions:
For details on the principle see Galuzzi et al. 2024,Journal of Biomedical Informatics.
[rxnsMetId, producingMet, matched] = getRxnIDs(BRCAProject, referenceModel, ["Glycolysis.*"]);
visSingleRxnSamplingDistribution(BRCAProject, comparisonName, rxnsMetId(1), ["Glycolysis"], referenceModel, true)
For more ways on how to use the visualizations to investigate the models see our cheatsheet below:
Upcoming features
The following are planned for future integration:
- IDARE output — generation of interactive pathway visualizations using the IDARE toolbox
- Report generation — automated PDF report for model comparisons, similar to
writeAnalysisReportfor single model analysis